
AWS Certified DevOps Engineer - Professional (DOP-C02) Free Practice Exam and Practice Test
1040 DOP-C02 practice questions, updated , in an exam simulator that mirrors the real exam: its domains, its question types and its timing, with an explanation for every answer.
DOP-C02 example questions
One example question per domain from the DOP-C02 question bank, with the correct answer and its explanation. Sign in to the simulator to answer them with all answer options.
A company uses AWS CodeDeploy to deploy a Lambda function through a production alias with a canary configuration that shifts 10% of traffic for 10 minutes before shifting the remaining traffic. The deployment group monitors a CloudWatch alarm and has automatic rollback enabled when the alarm enters ALARM. The alarm calculates 100 × SUM(Errors) / SUM(Invocations) for the production alias and uses a 5% threshold.
During a deployment, the candidate version consistently fails 30% of its invocations, but the previous version has no errors. The alarm reports approximately 3%, remains OK, and allows the deployment to continue. Traffic volume is high enough to provide representative measurements for both versions every minute.
A DevOps engineer must make the deployment stop and roll back when the candidate version's error rate exceeds 5%, without changing the traffic-shifting schedule or treating a candidate error rate below 5% as a failure. Which solution meets these requirements?
Show answer
CORRECT ANSWERFor each deployment, configure an alarm using the Errors and Invocations metric series that identify the candidate ExecutedVersion invoked through the production alias. Calculate 100 × SUM(Errors) / SUM(Invocations) for that version, apply the 5% threshold, and associate the alarm with the deployment group before traffic shifting begins.
Version-specific metric series isolate the candidate's actual error rate instead of combining its results with the previous version. Using candidate-version errors and candidate-version invocations produces approximately 30% in this scenario. Associating the alarm with the deployment group allows the existing alarm-triggered automatic rollback configuration to act on the breach.
A company must automate configuration updates for 50,000 independent application environments. An Amazon S3 object contains a 40-MB JSON array that identifies the environments. For each environment, the automation must initiate an infrastructure update, wait for completion, and validate the configuration. Each environment's workflow takes 10–20 minutes and produces at least 2 KB of diagnostic output.
The solution must support 100 concurrently running environment workflows while enforcing that concurrency limit. It must retain diagnostic output in S3 and continue processing if no more than 1% of the environment workflows fail. The DevOps engineer wants to minimize custom orchestration code.
Which solution meets these requirements?
Show answer
CORRECT ANSWERCreate a Standard state machine with a Distributed Map state. Use an S3 ItemReader to read the manifest, run Standard child workflows, set MaxConcurrency to 100 and ToleratedFailurePercentage to 1, and configure ResultWriter to export results to S3.
Distributed Map can read a large dataset directly from S3 without loading the entire manifest into the parent execution's payload. Standard child workflows support the 10–20-minute duration. MaxConcurrency limits concurrent child executions to 100, and ToleratedFailurePercentage allows the Map Run to continue while failures remain within the specified percentage. ResultWriter exports child workflow results to S3 instead of accumulating an oversized result in the parent.
A company runs a stateless HTTPS service on EC2 instances in two Availability Zones behind one Application Load Balancer (ALB). A listener rule uses a weighted forward action to send 50% of requests to each of two target groups. Each target group contains only the instances in one Availability Zone. Cross-zone load balancing is enabled, and target group stickiness is disabled.
During a resilience test, all application processes in one Availability Zone fail. The ALB marks every target in that zone's target group unhealthy, but some new requests continue to fail. The other target group remains healthy and has sufficient capacity to serve the entire workload.
The company requires new requests to use the remaining healthy targets after health checks detect this type of failure in either zone. During normal operation, both zones must serve traffic. The solution must retain the existing ALB and DNS configuration and must not require incident-time configuration changes or custom failover automation.
Which change meets these requirements?
Show answer
CORRECT ANSWERRegister the instances from both Availability Zones in one target group, retain cross-zone load balancing, and update the listener rule to forward all requests to that target group.
A single target group gives the ALB one pool of targets across both zones. With cross-zone load balancing enabled, ALB nodes can route new requests to healthy targets in either zone. When one zone's targets become unhealthy, the surviving healthy targets remain eligible without changing listener weights or DNS.
A company must notify its security team whenever an assumed-role session successfully calls StopLogging or DeleteTrail in an AWS account, except when the session belongs to the approved TrailMaintenance role. Failed API calls must not generate notifications. All relevant calls use assumed-role credentials, and failed calls include an errorCode field in their CloudTrail events.
A trail is already logging all write management events. An Amazon SNS topic has confirmed email subscriptions and a resource policy that permits EventBridge to publish notifications. The approved role ARN is arn:aws:iam::123456789012:role/TrailMaintenance.
A DevOps engineer will create an EventBridge rule on the default event bus and configure the SNS topic as its target. Which event pattern meets the requirements?
Show answer
CORRECT ANSWERUse this event pattern: {"source":["aws.cloudtrail"],"detail-type":["AWS API Call via CloudTrail"],"detail":{"eventSource":["cloudtrail.amazonaws.com"],"eventName":["StopLogging","DeleteTrail"],"errorCode":[{"exists":false}],"userIdentity":{"sessionContext":{"sessionIssuer":{"arn":[{"anything-but":"arn:aws:iam::123456789012:role/TrailMaintenance"}]}}}}}
The pattern matches either specified API operation and requires errorCode to be absent, selecting successful calls. For assumed-role credentials, sessionContext.sessionIssuer.arn identifies the underlying IAM role. The anything-but comparison therefore excludes every session issued by TrailMaintenance. Matching events are routed to the SNS topic.
A company runs an Amazon ECS service on EC2 instances supplied by an Auto Scaling group capacity provider. Managed scaling is enabled with a target capacity of 100%. The service uses only this capacity provider. The Auto Scaling group has a desired capacity of 4 and a maximum capacity of 20. Its mixed instances policy allows m5.large instances (2 vCPUs, 8 GiB of memory) and m5.2xlarge instances (8 vCPUs, 32 GiB of memory), without instance weights.
Each task requires 4 vCPUs and 16 GiB of memory. The four existing instances are m5.2xlarge instances and have no remaining capacity for additional tasks. After the service's desired count increases, additional tasks remain in PROVISIONING. The capacity provider's CapacityProviderReservation metric remains at its target, and no scale-out activity occurs. Subnet addresses, service quotas, and instance availability are not limiting factors.
The task resource requirements cannot be reduced. A DevOps engineer must correct the configuration so that managed scaling automatically provisions capacity for these tasks.
Which change meets this requirement?
Show answer
CORRECT ANSWERRemove m5.large from the Auto Scaling group's allowed instance types, and ensure that every remaining allowed instance type can accommodate at least one task.
ECS managed scaling checks whether provisioning tasks can fit on the smallest instance type allowed by the Auto Scaling group. Tasks that cannot fit are excluded from the scale-out calculation and can remain in PROVISIONING without triggering scaling. The m5.large cannot accommodate this task. Allowing only compatible instance types removes this constraint so that managed scaling can provision the required capacity.
A company runs thousands of short-duration data-processing workers on Amazon EC2. The workers authenticate to an internal service by using mutual TLS. An existing workload controller generates certificate signing requests and can install replacement certificates without restarting the workers.
A new security standard requires worker certificates to be valid for 12 hours and replaced every 6 hours. The issuing service must reject any request for a worker certificate with a validity period longer than 7 days, even if a defect in the controller requests a longer period. Issuance roles cannot change the issuing CA's configuration. The company wants a managed CA and does not require revocation because the service's security design relies on short certificate lifetimes.
Which solution meets these requirements?
Show answer
CORRECT ANSWERCreate an AWS Private CA in short-lived certificate mode. Configure the controller to call IssueCertificate with a 12-hour validity period, retrieve the issued certificate, and install a replacement every 6 hours. Monitor issuance and installation failures.
Short-lived certificate mode enforces a maximum issued-certificate validity of 7 days. Direct AWS Private CA API issuance supports the required 12-hour certificates, while the existing controller can automate replacement every 6 hours. Monitoring the workflow is important because certificates issued directly through the private CA API do not receive ACM managed renewal.
Free DOP-C02 cheat sheets
One PDF per exam domain: the domain's task statements, each drawn with its services and exam traps, then the concepts and core services to remember.
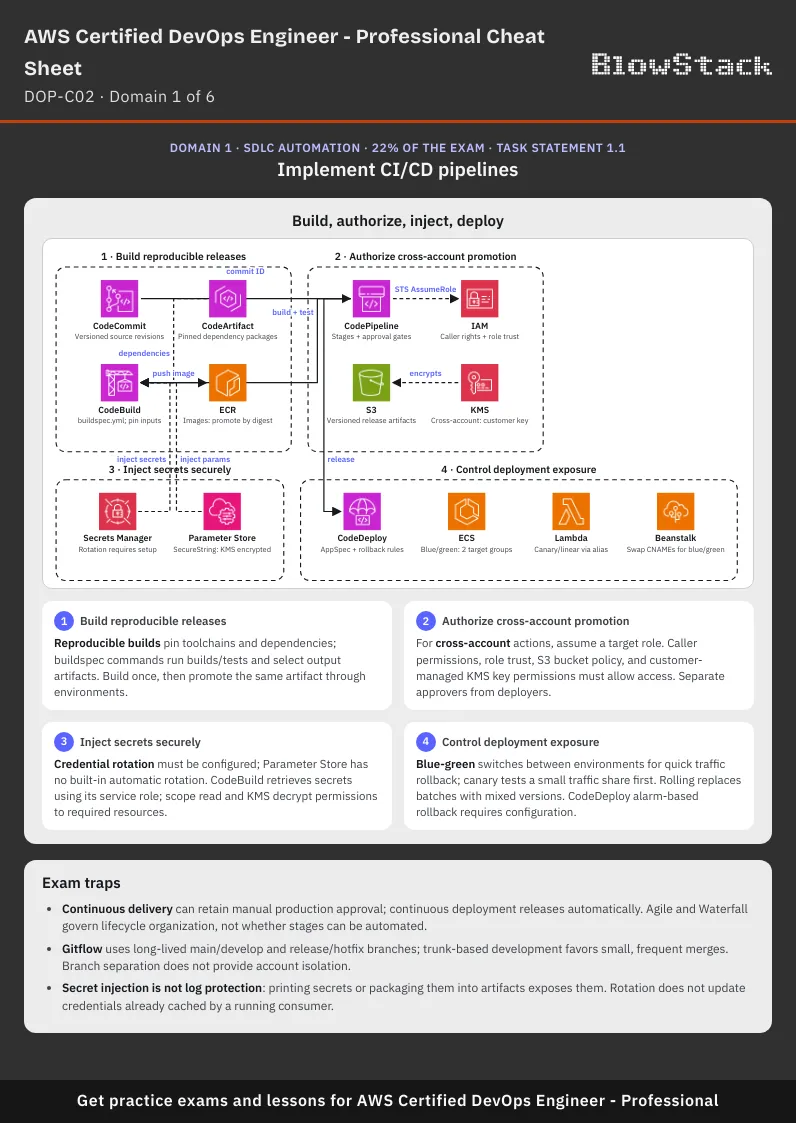
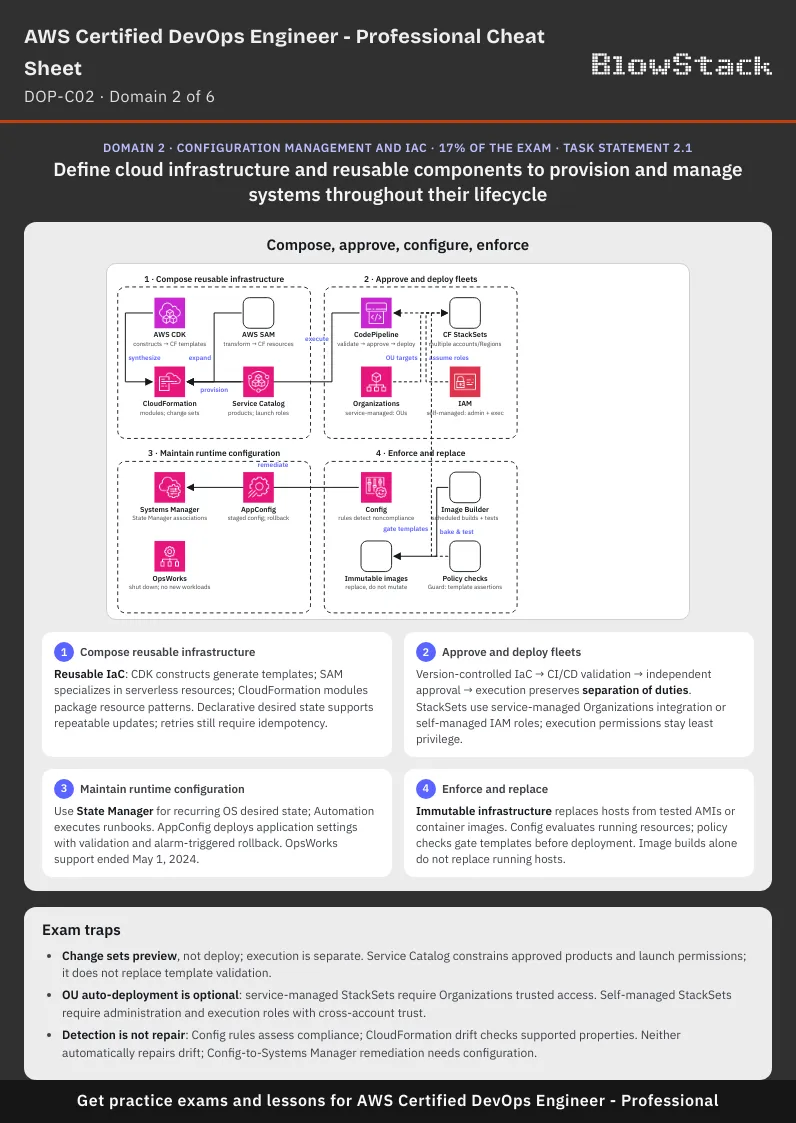
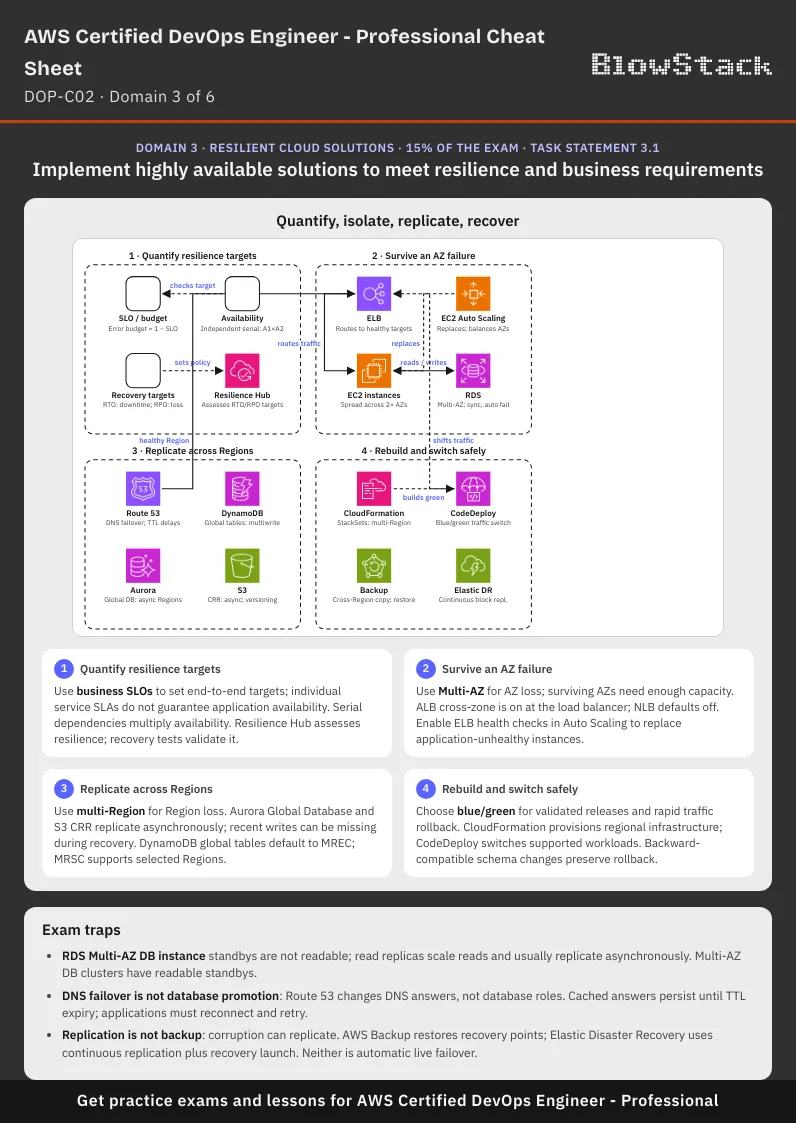
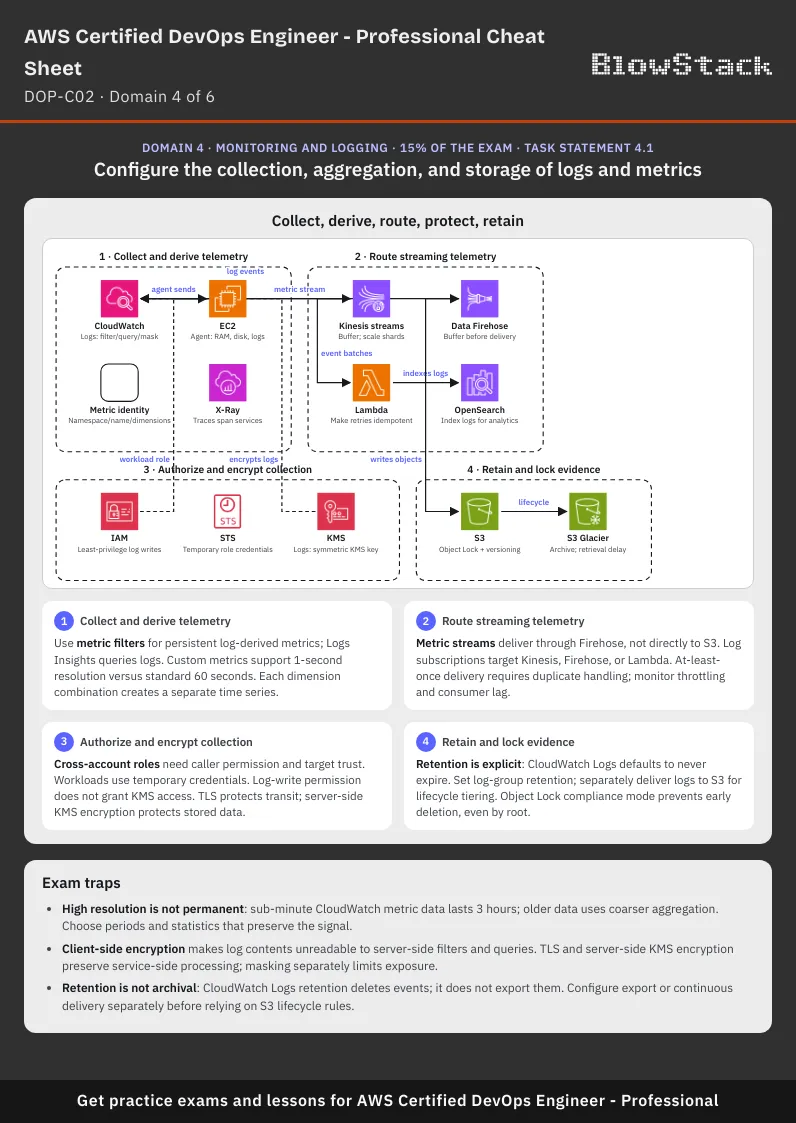
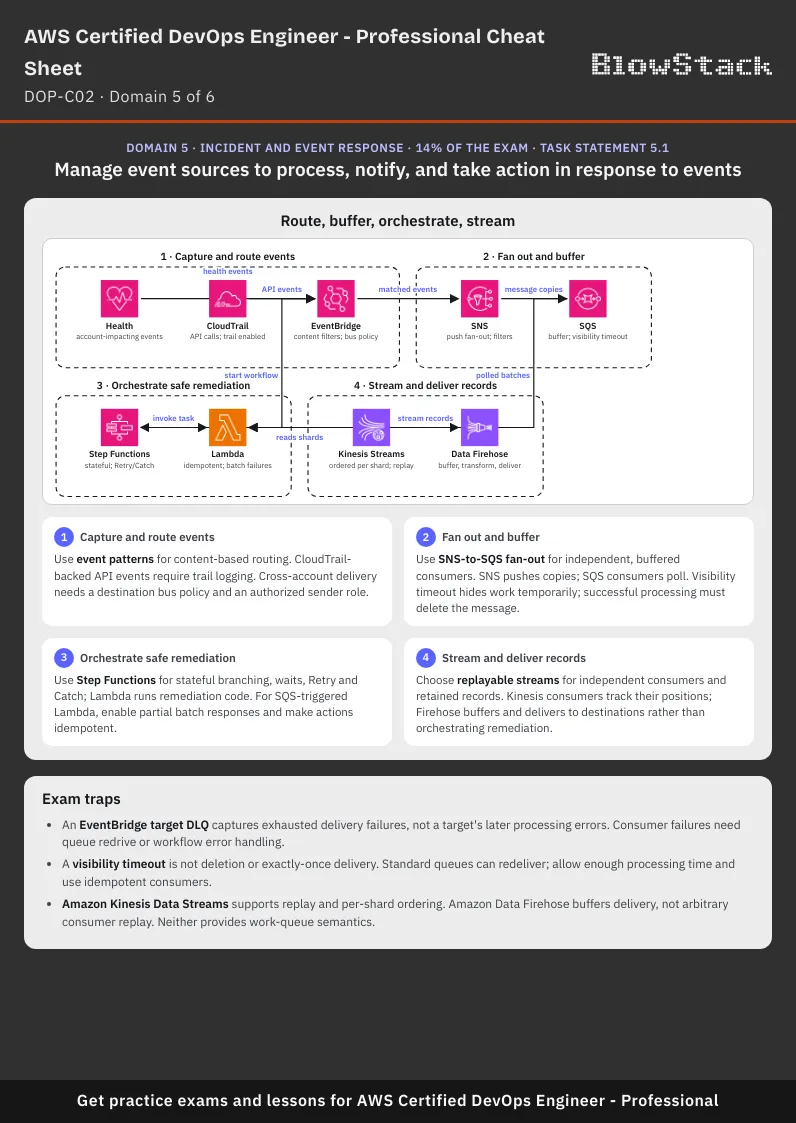
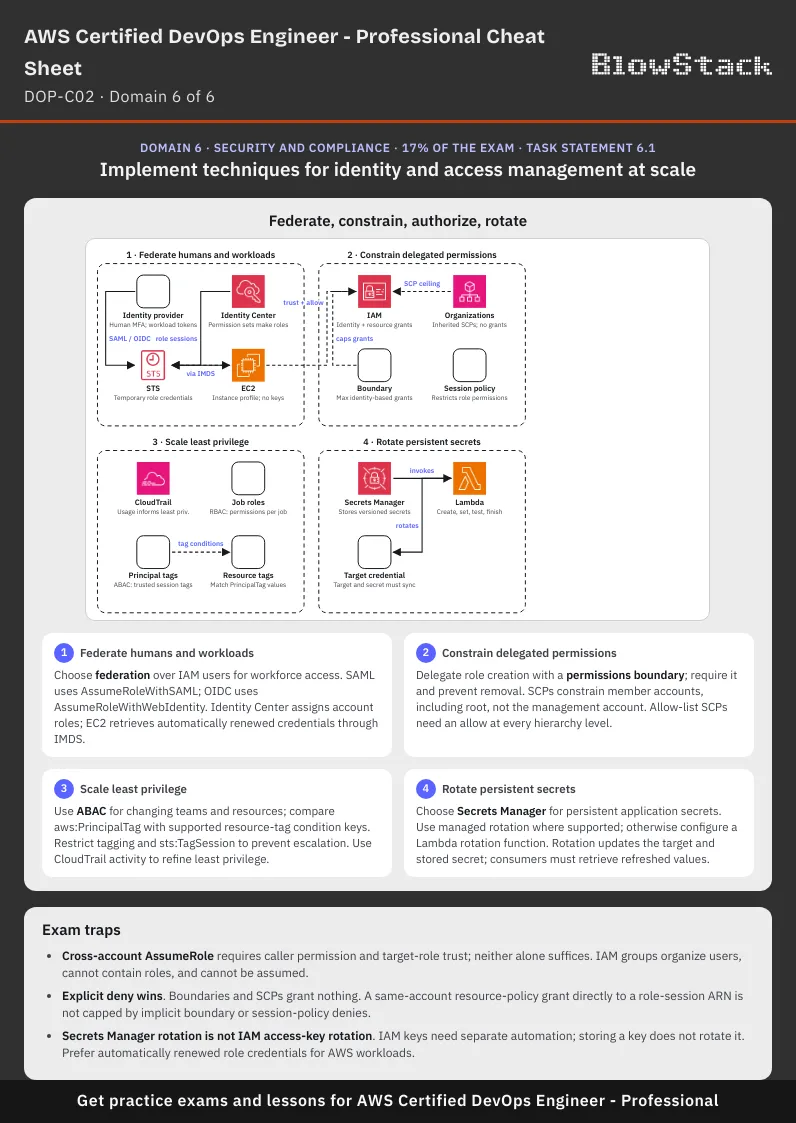
Exam domains
The DOP-C02 questions are grouped into 6 domains divided into 19 tasks.
- Implement CI/CD pipelines
- Integrate automated testing into CI/CD pipelines
- Build and manage artifacts
- Implement deployment strategies for instance, container, and serverless environments
- Define cloud infrastructure and reusable components to provision and manage systems throughout their lifecycle
- Deploy automation to create, onboard, and secure AWS accounts in a multi-account or multi-Region environment
- Design and build automated solutions for complex tasks and large-scale environments
- Implement highly available solutions to meet resilience and business requirements
- Implement solutions that are scalable to meet business requirements
- Implement automated recovery processes to meet RTO and RPO requirements
- Configure the collection, aggregation, and storage of logs and metrics
- Audit, monitor, and analyze logs and metrics to detect issues
- Automate monitoring and event management of complex environments
- Manage event sources to process, notify, and take action in response to events
- Implement configuration changes in response to events
- Troubleshoot system and application failures
- Implement techniques for identity and access management at scale
- Apply automation for security controls and data protection
- Implement security monitoring and auditing solutions
Exam mode and practice mode
| Exam mode | Practice mode | |
|---|---|---|
| Questions count | 75 | 1 - 75 |
| Time limit | 180 minutes | Optional, 10 - 200 minutes |
| Exam scope | 6 domains with the official questions ratio | Selected domains with the official questions ratio |
| Correct answers | After exam submission | After exam submission or after each answer |
| Question types | Single answer and multiple answer | Single answer, multiple answer or all types |
| Question hints | Never | Optional |
| Question domain | Revealed after exam submission | Revealed after submission or during the exam |
| Scoring | 15 of 75 questions do not count towards the result | Official AWS method or mathematical mean |
See all simulator features on the AWS Exam Simulator page.
About the DOP-C02 exam
The AWS Certified DevOps Engineer - Professional (DOP-C02) certification is designed for individuals with extensive experience in managing AWS environments. It assesses your ability to implement and manage continuous delivery systems and methodologies on AWS. Before attempting this certification, it is recommended to have a solid understanding of modern development and operations processes and methodologies, as well as experience in developing code in at least one high-level programming language and managing automated infrastructures.
The exam consists of 75 questions in multiple-choice and multiple-response formats. You have 180 minutes to complete the exam, which can be taken at a Pearson VUE testing center or online with a proctor. The cost of the exam is $300, and it is available in several languages, including English, Japanese, Korean, and Simplified Chinese. To pass, you need a score of 750 out of 1000.
This certification focuses on six main areas: automating the software development lifecycle (SDLC), managing infrastructure as code (IaC), creating resilient cloud solutions, monitoring and logging, incident and event response, and ensuring security and compliance. Key AWS services you need to be familiar with include AWS CodeCommit, AWS CodeBuild, AWS CodeDeploy, AWS CloudFormation, Amazon CloudWatch, AWS Lambda, and AWS IAM.
Preparing for this certification involves reviewing the official exam guide, which details the domains covered and their respective weightages. Practical experience is crucial, so setting up a lab environment to practice using AWS services is highly recommended. Additionally, enrolling in relevant training courses, such as those offered by experts like Stephane Maarek and Adrian Cantrill, can provide valuable insights and hands-on experience. Practice exams, like those by Jon Bonso, can help you get accustomed to the exam format and identify areas where you need to focus more.
Overall, achieving the AWS Certified DevOps Engineer - Professional certification demonstrates your proficiency in managing and automating AWS environments using DevOps principles, making it a valuable credential for advancing your career in cloud computing and DevOps.
Technologies and concepts
Acceptance Testing
Acceptance testing evaluates observable system behavior against requirements that stakeholders consider necessary for release or delivery. In CI/CD pipelines, automated acceptance tests provide a repeatable release gate, complementing lower-level technical tests and any required human acceptance decisions.
Access Control
Access control turns security requirements into enforceable permissions for people, applications, and cloud services. It limits unauthorized activity while preserving legitimate operations, including the ability to deliver logs, run health checks, and investigate incidents.
Active-Active Architecture
Active-active architecture combines availability and scalability by keeping two or more environments actively serving production requests rather than reserving one solely for recovery. Across cloud Regions, it can reduce user latency and support regional disaster recovery, but it requires deliberate traffic management, data consistency, and capacity planning.
Agile Development
Agile development organizes work into small, valuable increments rather than treating requirements, implementation, and validation as a single long sequence. In cloud engineering, it helps teams use automated testing, repeatable environments, and delivery pipelines to validate changes quickly while controlling operational risk.
Analytics
Analytics turns raw records, events, and measurements into useful information through querying, aggregation, statistical analysis, and visualization. In the cloud, managed storage and processing services let engineers analyze changing data volumes without building every infrastructure component themselves.
Anomaly Detection
Anomaly detection compares observed activity with an established baseline, statistical model, or expected pattern to identify unusual behavior. In cloud security, it helps engineers detect potentially compromised identities, unexpected network activity, and abnormal resource usage that fixed rules alone might miss. An anomaly is evidence for investigation, not proof of an attack.
APIs
An application programming interface defines available operations, accepted inputs, responses, and error behavior. In the cloud, APIs enable applications and automation tools to provision resources, configure services, and process data, making them the foundation of programmatic access.
Architecture Reviews
An architecture review identifies risks, examines design trade-offs, and produces actionable improvements for a cloud workload. Frameworks such as the AWS Well-Architected Framework provide a consistent way to evaluate quality across multiple dimensions rather than focusing only on whether an application works.
At-Least-Once Delivery
At-least-once delivery uses retries, acknowledgments, and durable buffering to favor delivery reliability over duplicate avoidance. It is common in real-time log ingestion, where consumers must tolerate repeated records without inflating metrics, duplicating alerts, or corrupting downstream state.
Attribute-Based Access Control
ABAC expresses access rules using attributes such as project, department, environment, or data classification instead of maintaining separate permissions for every identity and resource. In cloud environments, trusted identity attributes and resource tags can make permissions scale with changing teams and infrastructure, provided attribute assignment and modification are tightly controlled.
Audit Logging
Audit logging creates an evidence trail showing who or what performed an action, when it occurred, which resource was affected, and what the outcome was. In cloud environments, effective auditing requires selecting complementary log sources and protecting their delivery, retention, and accessibility across accounts, Regions, and workloads.
AWS global infrastructure
This infrastructure lets engineers choose where applications run, how they tolerate failures, and how closely they serve users. Understanding its geographic and operational boundaries is essential for designing availability, latency, disaster recovery, and data residency controls.
Backpressure
Backpressure keeps data producers from overwhelming consumers, processing stages, or storage systems when incoming work exceeds available capacity. It helps pipelines remain stable during traffic bursts, throttling, and slow transformations, but requires explicit policies for buffering, retries, and overload.
Backup and Restore
Backups preserve earlier states of data so engineers can recover from accidental deletion, application errors, ransomware, or infrastructure failures. Effective protection requires more than creating copies: it also requires suitable retention, protected access, and tested restoration procedures that meet business recovery objectives.
Backup Isolation
Backup isolation creates independent security and failure boundaries around backup data, retention settings, administrative identities, and encryption keys. It matters because ransomware, stolen credentials, accidental deletion, and infrastructure failures can otherwise affect both live data and the copies needed to recover it.
Blast Radius
Blast radius describes both the potential reach of an incident and the impact actually observed during investigation. Cloud architectures reduce it through isolation, restricted permissions, and controlled dependencies, while incident responders use evidence to determine which boundaries an event has crossed.
Block Storage
Block storage provides disk-like capacity for operating systems, databases, and applications that need direct reads and writes to specific locations. In the cloud, it can be delivered through persistent network-attached volumes or temporary disks attached to a compute host, making durability, performance, and lifecycle behavior important selection criteria.
Blue-Green Deployment
Two independently deployable environments allow engineers to validate a replacement release while the existing release continues serving users. Switching traffic rather than modifying the live environment reduces deployment disruption and can enable fast rollback, provided data and dependencies remain compatible.
Blue-Green Deployments
Two environments coexist during a release: blue serves the current version while green runs the replacement version for validation and promotion. Separating deployment from traffic cutover reduces release-related downtime and enables rapid traffic rollback, provided application state and dependencies remain compatible.
Caching
A cache serves repeated requests without always accessing the original data source or recomputing a result. In cloud architectures, caching can reduce latency, origin load, and data transfer, but it requires deliberate decisions about freshness, capacity, security, and failure behavior.
Canary Deployment
A canary deployment runs the current and candidate versions concurrently, exposing only a limited share of real requests or users to the candidate. Engineers use production metrics and explicit acceptance criteria to decide whether to promote the candidate or redirect traffic to the stable version, reducing the impact of faulty releases.
Certificate management
It covers certificate issuance, validation, deployment, renewal, revocation, and retirement, together with protection of the keys and trust chains that make certificates useful. In cloud environments, effective certificate management prevents outages from expired certificates and supports authenticated, encrypted communication across public endpoints, internal services, accounts, and Regions.
Chaos Engineering
Chaos engineering uses explicit hypotheses, realistic faults, and measurable outcomes to uncover weaknesses before an unplanned incident exposes them. In cloud environments, it validates both technical resilience and incident response procedures, including detection, escalation, containment, recovery, and communication.
CI/CD
Continuous integration validates frequently merged code changes through automated builds and tests, while continuous delivery or continuous deployment automates the path toward production. Together, these practices shorten feedback cycles, make releases more repeatable, and reduce the risks associated with large, manually executed changes.
Client-Side Encryption
The receiving service stores ciphertext rather than the original plaintext, and authorized clients decrypt the data when they retrieve it. This separates access to stored data from access to its plaintext, but requires deliberate choices about key custody, application security, and recovery.
Code Coverage
Code coverage identifies which parts of a program a test suite exercises and which remain untested. In CI/CD pipelines, coverage reports and enforceable thresholds help teams detect testing gaps before deployment, but coverage alone does not prove that software behaves correctly.
Composite Availability
A cloud application can be unavailable even when most of its components are healthy, because successful requests may require several services to work together. Composite availability helps engineers evaluate architecture choices, estimate whether business availability targets are achievable, and distinguish application commitments from individual provider SLAs.
Configuration Drift
Configuration drift occurs when running infrastructure, operating systems, or applications no longer match their intended configuration, often because of manual changes, competing automation, or incomplete deployments. Detecting and managing drift helps engineers preserve security controls, reproduce environments, and investigate unexpected changes before they cause incidents.
Configuration Management
Configuration management makes infrastructure and application settings repeatable, auditable, and easier to recover when changes cause problems. In the cloud, it is a shared responsibility: the provider configures its underlying infrastructure, while customers manage the settings and software within their control.
Containers
Containers provide a repeatable way to build, distribute, and run software across development and cloud environments. They improve deployment consistency and resource utilization, but require explicit controls for image security, runtime isolation, networking, identity, and persistent data.
Content-Based Routing
Instead of distributing requests solely by availability or load, content-based routing selects a destination suited to each request’s characteristics. In generative AI applications, it can match tasks to specialized foundation models while balancing quality, latency, cost, and security constraints.
Credential Management
Credentials include passwords, access keys, session tokens, and other material used to prove an identity. Managing their lifecycle reduces credential theft, limits the impact of compromise, and keeps applications working when credentials change or expire.
Credential Rotation
Passwords, access keys, tokens, and application secrets can be exposed through compromised systems, accidental disclosure, or excessive distribution. Rotation limits how long a persistent credential remains usable, but it must coordinate changes across the identity system, secret storage, and consuming applications to avoid outages.
Cross-Account Access
Cloud accounts create administrative and security boundaries, but shared services, deployment pipelines, and operational teams often need controlled access across them. Cross-account access establishes that authorization without requiring shared credentials or moving resources into the same account.
Data Archiving
Archiving moves data out of active workflows while preserving its integrity, context, and accessibility for a defined retention period. In the cloud, object storage and archival storage tiers help reduce storage costs, but engineers must balance those savings against retrieval delays, access charges, and retention obligations.
Data Classification
Classification connects the value and risk of information to decisions about access, storage, monitoring, retention, and disposal. In cloud workloads, it helps engineers determine which activities require audit records, which changes should trigger alerts, and how quickly security teams must respond.
Data Locality
In cloud architectures, locality can mean using the same Region, Availability Zone, or processing environment, depending on the workload. It matters because network boundaries affect performance and billing, while replication and geographic distribution introduce trade-offs involving resilience, consistency, and data residency.
Data Masking
Data masking reduces unnecessary exposure of confidential information in logs, messages, query results, and nonproduction datasets. It complements encryption and access control by limiting which sensitive values users and downstream systems can actually see.
Data Retention
Retention policies balance business needs, recovery requirements, legal obligations, privacy, and storage cost. In the cloud, engineers implement them through lifecycle rules, backup schedules, retention periods, deletion controls, and exceptions such as legal holds.
Database Replication
Database replication maintains additional copies of database data by transferring an initial dataset and subsequent changes. In cloud migrations, it lets the source database continue serving applications while a target catches up, reducing the downtime needed to switch environments. Replication also supports resilience and distributed reads, but its consistency, recovery, and cost characteristics depend on the implementation.
DDoS Mitigation
Distributed denial-of-service attacks use many sources to exhaust network bandwidth, connection capacity, or application resources. Mitigation matches defenses to the threatened layer, rejects malicious traffic before it reaches constrained resources, and preserves access for legitimate users.
Declarative Programming
Instead of prescribing each operation in order, engineers define resources, relationships, constraints, or interface states that a tool interprets. This approach supports repeatable infrastructure provisioning, reusable application components, API contracts, and visual AI workflows, but still requires testing, security controls, and lifecycle management.
Defense in Depth
Defense in Depth combines preventive, detective, and response controls across network boundaries, identities, applications, hosts, and data. It reduces dependence on any single safeguard and limits the impact of successful attacks, configuration mistakes, and compromised credentials.
Dependency Pinning
Dependency pinning replaces floating dependency selections with controlled references recorded in manifests, lockfiles, or build configuration. It improves artifact consistency, troubleshooting, and rollback, but requires deliberate updates to incorporate security fixes and compatibility changes.
Deployment Rollback
Rollback limits the impact of a faulty release by returning workloads to a known-good deployment state. It depends on preserved artifacts, compatible dependencies and data, reliable failure signals, and a tested recovery procedure rather than simply undoing a source-code change.
Digital Signatures
A digital signature allows a recipient to detect changes to signed data and verify that the signature was produced by the holder of a particular private key. In cloud environments, signatures help validate software releases, stored files, and audit records, provided that verifiers trust the signing key and enforce verification.
Disaster recovery
Disaster recovery combines recoverable data, replacement infrastructure, documented procedures, and testing to restore technology services after failures, attacks, or operational mistakes. In the cloud, it uses capabilities such as backups, replication, automated provisioning, and geographically separate deployments to balance recovery requirements against cost and complexity.
Distributed Tracing
A distributed trace connects individual operations across services into a single view of a request's execution. It helps engineers troubleshoot cloud applications whose behavior cannot be understood from one server's logs or metrics alone.
Effective Permissions
Assigned permissions do not necessarily equal usable access: authorization combines grants with organizational controls, resource policies, session restrictions, and request context. Understanding the resulting permissions helps engineers design least-privilege access and diagnose why an apparently allowed operation fails.
Elasticity
Elasticity aligns available capacity with actual demand, adding resources during busy periods and releasing them when demand falls. In the cloud, automated provisioning and usage-based pricing can reduce idle capacity and avoid purchasing infrastructure for occasional peaks, while helping applications maintain performance.
Encryption
Encryption helps prevent unauthorized parties from understanding data stored in cloud systems or transmitted over networks. Its effectiveness depends on protecting cryptographic keys, controlling decryption permissions, and applying encryption wherever sensitive data travels or persists.
Encryption at Rest
Encryption at rest protects data stored in objects, disks, databases, snapshots, and backups from disclosure when the underlying storage is accessed without the required keys. In cloud environments, it combines storage encryption with key management and access controls, but it does not replace authorization, backups, or encryption in transit.
Encryption in Transit
Encryption in transit prevents observers on a network path from reading protected data and, with correctly configured secure protocols, helps detect tampering and authenticate communicating endpoints. In cloud architectures, it applies to internet traffic, internal service communication, and hybrid or multi-cloud connections, independently of encryption at rest.
End-to-End Testing
End-to-end testing checks whether an application achieves the intended user outcome when its components work together under realistic conditions. For foundation model applications, it evaluates the combined behavior of prompts, retrieval, models, tools, safeguards, and workflows rather than relying on model benchmarks alone.
Envelope Encryption
Envelope encryption separates bulk data encryption from the protection and management of encryption keys. It combines efficient local encryption with centralized key controls, allowing cloud systems to protect large datasets without sending every byte through a key management service.
Error Budgets
An error budget translates a reliability target into an allowance for failed requests, excessive latency, or unavailable time. Teams use that allowance to balance delivery speed against operational risk, prioritize resilience work, and protect customer-facing service-level commitments.
Event Correlation
Individual logs and alerts often describe only fragments of an incident or operational failure. Event correlation combines those fragments into a contextual sequence, helping engineers detect suspicious behavior, investigate causes, and reduce duplicate or low-value alerts.
Event Streaming
Producers append events to a stream, while consumers read and process those events independently, often within seconds or less. This decouples event generation from downstream processing and supports incident detection, operational analytics, and automated responses without requiring producers to know every consumer.
Event-Driven Architecture
An event records something that has happened, such as an order being placed, a file being uploaded, or a monitoring threshold being crossed. By separating event producers from consumers, this architecture lets cloud applications process work independently, absorb traffic spikes, and deliver notifications without requiring every component to respond at the same time.
Eventual Consistency
A successful write does not necessarily become visible immediately through every replica or read path. This model supports asynchronous replication and scalable reads, but engineers must account for stale results, replication lag, and possible data loss when failing over to an asynchronous replica.
Evidence Integrity
Reliable incident response depends on logs and other artifacts remaining authentic, traceable, and protected throughout collection, storage, transfer, and analysis. Evidence integrity combines tamper detection, preservation controls, and documented handling so engineers can reconstruct events and support defensible conclusions.
Exception Handling
Data pipelines encounter malformed records, unavailable dependencies, permission errors, and unexpected program behavior. Exception handling separates failure paths from normal processing and makes recovery decisions explicit, helping engineers protect data integrity and operate reliable ingestion and transformation workloads.
Exit Codes
By convention, an exit code of zero indicates success, while a nonzero value indicates an error or another condition defined by the program. CI/CD pipelines use these values to evaluate automated tests, enforce deployment gates, and interpret health-check results, making correct propagation essential to reliable automation.
Explicit Deny Precedence
In a deny-overrides authorization model, a request fails whenever an applicable policy explicitly denies it, even if another policy allows it. This enables enforceable security guardrails, but troubleshooting requires identifying the denying statement and its evaluation context rather than simply adding permissions.
Exponential Backoff
Exponential backoff gives an overloaded or temporarily unavailable dependency time to recover instead of receiving immediate repeated requests. In cloud systems, it is typically combined with randomized delays, retry limits, and safe request semantics to handle throttling and transient failures without amplifying an outage.
Fail-Fast
Fail-fast systems expose problems close to their cause instead of allowing invalid work to continue through later processing or deployment stages. In CI/CD pipelines, automated checks communicate failure through exit codes and action status so defective changes do not advance to production.
Failover
Failover uses redundant resources, health detection, and a mechanism for transferring work to reduce interruptions when components fail. In cloud architectures, distributing those resources across multiple Availability Zones helps maintain availability when an instance or an entire zone becomes unavailable.
False Positives
Security tools identify patterns and conditions that require validation, not automatic acceptance as confirmed incidents. Distinguishing false positives from genuine threats and accurately detected but authorized activity helps responders assess scope and impact without wasting investigation time or disrupting legitimate workloads.
Fan-Out
Fan-out lets a producer trigger several independent activities without performing each activity itself. It supports parallel processing and independently scalable consumers, but requires deliberate handling of delivery failures, duplicate messages, ordering, and downstream capacity.
Fault Isolation
Cloud systems use fault isolation to limit the scope of infrastructure failures, software defects, and resource exhaustion. Separating components into independent failure domains reduces correlated outages, but applications also need healthy alternatives and recovery mechanisms to remain available.
Fault Tolerance
Fault-tolerant systems use redundancy, failure isolation, and automated handling of faults to keep component failures from becoming service failures. In the cloud, this capability also determines which workloads can safely use interruptible compute capacity and which need a more predictable capacity strategy.
Gitflow
Gitflow uses long-lived production and integration branches alongside temporary feature, release, and hotfix branches. It helps teams coordinate scheduled releases and map version-control events to CI/CD pipelines, but adds merge overhead and requires explicit rules for promoting tested artifacts between environments.
Health Checks
Health checks turn observations about infrastructure and applications into signals for traffic routing, deployment decisions, and automated recovery. Their value depends on testing the right behavior and connecting failures to appropriate actions without causing unnecessary restarts or cascading outages.
High availability
High availability reduces service interruptions by combining redundant components, isolated failure domains, health monitoring, and recovery mechanisms. In the cloud, it commonly involves distributing workloads across multiple Availability Zones so that a failure in one location does not stop the entire application.
Idempotency
Idempotency makes retries safe when requests time out, events arrive more than once, or automation restarts after a failure. In incident response, it prevents repeated remediation attempts from creating duplicate resources, reversing containment, or causing additional disruption.
Identity Federation
Federation separates where an identity is authenticated from where that identity accesses resources, using established trust and verifiable identity assertions or tokens. It enables centralized sign-in for employees, customers, and workloads while letting each application or cloud account retain control over authorization.
Immutable Infrastructure
Changes to operating systems, application dependencies, and security configuration are built into tested machine or container images and deployed as replacements. This reduces configuration drift and makes recovery more repeatable, provided that persistent data, secrets, and incident evidence are managed separately.
Immutable Storage
Immutable storage uses storage-enforced controls to protect retained records from accidental changes, malicious deletion, and unauthorized replacement. For security logging, it preserves evidence for investigations and compliance, while separate controls must ensure that logs are collected completely, remain readable, and can be analyzed safely.
Infrastructure as code (IaC)
IaC turns infrastructure definitions into repeatable deployment processes that can be reviewed, tested, and automated. It helps engineers create consistent environments, reduce manual errors, and apply security standards across accounts while maintaining a traceable history of changes.
Integration Testing
Components that pass isolated tests can still fail when combined because of incompatible schemas, incorrect configuration, permissions, network restrictions, or unexpected dependency behavior. Integration testing exercises these boundaries before changes reach production, making it an important quality gate for application delivery and data pipeline deployment.
IP Routing
IP routing determines how traffic moves between subnets, private networks, and the internet. In cloud environments, understanding routes, subnet associations, and gateways is essential for designing connectivity and diagnosing why a workload can or cannot reach a destination.
Key Management
Encryption depends on keeping cryptographic keys protected while making them available to authorized systems. Key management defines who controls those keys, how applications use them, and how access is audited and recovered, supporting both encryption at rest and encryption in transit.
Least privilege
Least privilege reduces the damage that compromised credentials, software defects, and operational mistakes can cause. In cloud environments, it applies to identity permissions, workload roles, administrative access, network connectivity, and organizational guardrails, and requires ongoing review as requirements change.
Load Balancing
A load balancer provides an entry point that directs traffic to a pool of application instances, containers, or other endpoints according to routing rules and health information. It helps applications handle demand and continue serving users when individual targets fail, but it does not create additional application capacity by itself.
Load Testing
Load testing applies representative traffic or work to an application and measures whether it meets business performance requirements. In cloud environments, it helps engineers identify bottlenecks, validate automatic scaling, and prevent performance regressions through repeatable CI/CD tests.
Log Normalization
Applications, operating systems, network devices, and cloud services describe events using different field names, formats, and meanings. Log normalization reconciles those differences so centralized detection rules and incident-response queries can operate across sources without repeatedly implementing source-specific logic.
Log Retention
Log retention determines how long operational, security, and audit records remain available for monitoring, investigation, and compliance. An effective policy balances required history and retrieval speed against storage cost, privacy obligations, and protection from unauthorized alteration or deletion.
Message Queuing
A message queue buffers work between applications so that producers and consumers do not need to run at the same speed or be available simultaneously. This helps absorb traffic spikes and isolate failures, but requires careful handling of retries, duplicate messages, processing delays, and retention limits.
Metric Cardinality
A metric such as request latency becomes many separate time series when it is partitioned by service, environment, endpoint, or instance. Controlling cardinality preserves useful diagnostic detail while limiting ingestion volume, storage costs, query work, and operational complexity.
Multi-Factor Authentication
Multi-factor authentication (MFA) combines factors such as something a person knows, possesses, or is, reducing the risk that a stolen password alone will allow unauthorized access. In cloud environments, it is especially important for privileged human access, root accounts, and sensitive operations, but it must be paired with appropriate authorization, session controls, and recovery procedures.
Network Segmentation
Network segmentation separates workloads by trust level, function, environment, or data sensitivity, then permits only the traffic required between them. It reduces exposure and limits lateral movement after a compromise, but effective segmentation requires enforced traffic controls rather than merely separate address ranges.
Object Storage
Object storage is designed to hold large collections of data without requiring applications to manage disks or traditional file systems. It is commonly used for images, videos, backups, logs, static website assets, and data lakes, with cost and access characteristics determined by the chosen storage class and configuration.
OpenID Connect
OpenID Connect (OIDC) standardizes authentication and identity claims so applications can rely on a shared identity provider instead of managing separate credentials. In cloud environments, it supports application sign-in and identity federation, including exchanges of trusted workload tokens for temporary cloud credentials.
Patch Management
Patch management keeps operating systems, applications, and dependencies updated through repeatable policies and deployment workflows. In cloud environments, responsibility depends on the service model: providers patch infrastructure they operate, while customers patch the software layers they control. Effective patching combines automation with risk-based prioritization, availability safeguards, and continuous validation.
Performance Benchmarking
Performance benchmarking establishes how quickly, reliably, and efficiently an application handles a specified workload. In cloud delivery pipelines, it helps engineers detect performance regressions, validate scaling behavior, and compare deployment options before promoting a release.
Pilot Light
A pilot light environment maintains the minimum foundation required to rebuild a production workload after a disaster, typically including continuously replicated data and predefined infrastructure. It balances ongoing cost against recovery speed, usually recovering faster than backup and restore but requiring more activation work than warm standby.
Policy as Code
Policy as Code turns written requirements into executable checks against infrastructure definitions, deployment plans, requests, or running resources. It helps teams apply consistent controls across accounts and environments, detect violations early, and retain reviewable evidence of policy changes and evaluation results.
Policy Inheritance
Cloud platforms use policy inheritance to apply common governance requirements across organizational hierarchies without configuring every account, project, or resource separately. The effective result depends on the policy type: some policies impose permission ceilings, while others merge configuration settings or allow controlled overrides.
Privilege Escalation
In cloud environments, an identity can gain unintended access without exploiting a software vulnerability: legitimate administrative APIs can become escalation paths when permissions are combined incorrectly. Preventing and investigating escalation requires evaluating effective authorization, identifying indirect paths to privileged identities, and correcting the permissions or trust relationships that enable them.
Public Key Infrastructure
Public Key Infrastructure (PKI) allows systems to verify that a public key belongs to the expected server, user, device, or organization. In cloud environments, it supports authenticated TLS connections, mutual TLS, and digital signatures while requiring careful protection of private keys and management of certificate lifecycles.
Publish-Subscribe Messaging
Publishers do not need to know which applications or people receive their messages, allowing producers and consumers to evolve independently. This pattern supports event distribution, application integration, and operational alerts, especially when one event must reach multiple independent recipients.
Quality Gates
A quality gate turns testing, evaluation, and operational requirements into enforceable promotion criteria. In cloud delivery, gates prevent unacceptable application, infrastructure, or generative AI changes from reaching broader environments while providing an auditable explanation for each release decision.
Rate Limiting
Rate limiting protects shared resources by restricting traffic according to a measured request rate, an allowed burst, and an enforcement policy. At the cloud edge, it helps reduce application-layer abuse and backend overload, but effective policies must distinguish legitimate traffic spikes from harmful behavior.
Recovery Point Objective
RPO defines how far back in time an organization can tolerate recovering its data after an incident. It guides backup frequency, replication design, and disaster recovery strategy, balancing the business impact of lost changes against protection costs.
Recovery Time Objective
RTO expresses how long a business can tolerate a workload being unavailable before the impact becomes unacceptable. Engineers use it to select recovery architectures, automate recovery procedures, and verify that applications and their dependencies can resume service within the required time.
Regular Expressions
Regular expressions let engineers recognize variable text without enumerating every possible value. In cloud operations, they help locate failures, extract fields from unstructured logs, and select events for monitoring or forwarding, but their syntax and capabilities depend on the system evaluating them.
Reproducible Builds
Reproducible builds control dependencies, toolchains, environment settings, and packaging behavior so that rebuilding a release produces the same artifact bytes. They help engineers detect unexpected changes, investigate software supply-chain risks, and generate dependable deployment artifacts, but require more than simply rerunning a successful CI job.
Resource Tagging
Tags describe business and operational attributes such as ownership, department, cost center, application, and environment without changing a resource’s function. A consistent tagging strategy supports cost allocation and resource management, while policy controls help prevent missing, misleading, or unauthorized tags.
Resource Utilization
Resource utilization shows how workloads consume CPU, memory, storage, network bandwidth, and other capacity. It informs rightsizing: selecting resource types, sizes, and quantities that meet performance and availability requirements without paying for unnecessary capacity.
Right-Sizing
Right-sizing uses observed demand and application requirements to choose appropriate compute, memory, storage, and throughput capacity. It reduces waste while preserving performance and reliability, and it requires regular review as workloads change.
Role-Based Access Control
Role-Based Access Control (RBAC) separates permission definitions from individual users or workloads, making access easier to administer and review. In cloud environments, it supports consistent authorization across teams and accounts, but requires carefully scoped roles and controlled assignments to prevent excessive privileges.
Rollback
Rollback limits the impact of defective deployments, unsafe configuration changes, and unsuccessful infrastructure updates by restoring an earlier working version or configuration. Effective rollback requires retained artifacts, compatible data and dependencies, clear failure signals, and a tested recovery procedure.
Rolling Deployment
A rolling deployment gradually updates or replaces running instances, tasks, or pods instead of changing the entire fleet at once. It limits simultaneous disruption and can avoid maintaining a complete second environment, but requires sufficient capacity, reliable health checks, and compatibility between application versions.
Runbooks
A runbook defines when to act, what steps to perform, how to verify success, and what to do if a step fails. In cloud recovery, tested runbooks reduce improvisation and help teams restore service within recovery time objective (RTO) and recovery point objective (RPO) requirements.
SAML 2.0
Security Assertion Markup Language 2.0 enables users to access cloud accounts and applications using an existing organizational identity rather than separate credentials for each destination. It supports centralized authentication and single sign-on, while the receiving service remains responsible for deciding what the user can access.
Separation of Duties
The idea is to prevent one identity from initiating, approving, executing, and concealing a sensitive action without independent oversight. In cloud environments, separate administrative roles, account boundaries, approval workflows, and protected audit records reduce the risk of fraud, mistakes, and compromised credentials.
Serverless
Serverless shifts infrastructure operations to the cloud provider so engineers can focus on application behavior, data, and configuration. It can reduce operational work and align costs with usage, but scaling behavior, billing, execution limits, and customer responsibilities vary by service.
Service Level Objectives
A service level objective (SLO) translates business expectations into a measurable target, such as successful request percentage or response time. SLOs guide architecture, monitoring, incident response, and spending by defining how much reliability a workload actually needs.
Shared File Systems
A shared file system lets applications on different servers work with the same files through familiar file operations rather than copying data between machines. In the cloud, managed file services support shared application content, user directories, and processing workloads while reducing the work of operating storage servers.
Stateful and Stateless Filtering
Stateful filters remember permitted traffic flows and use that context to recognize return traffic, while stateless filters evaluate each packet without remembering earlier exchanges. This distinction determines how engineers configure bidirectional access, troubleshoot blocked responses, and combine workload-level controls with subnet boundaries and inspection firewalls.
Statelessness
A stateless component processes each request using information supplied with that request and, when necessary, state retrieved from external systems. This makes processing instances interchangeable, simplifying horizontal scaling, failure recovery, and deployment without requiring the overall application to stop storing data.
Static Application Security Testing
Static Application Security Testing (SAST) identifies potentially vulnerable code paths, insecure programming patterns, and other implementation weaknesses before deployment. Integrating it into development environments and delivery pipelines helps engineers remediate problems early and prevent changes that violate security policy from reaching production.
Storage Tiering
Storage tiering balances storage cost against access latency, retrieval charges, and retention requirements. Cloud platforms implement it through explicit storage-class selection, lifecycle policies, or automatic movement based on access patterns, helping engineers avoid paying premium storage rates for rarely used data.
Stress Testing
Stress testing reveals how applications behave when demand exceeds available capacity, including whether they reject work safely, preserve data integrity, and recover after pressure subsides. Integrated into CI/CD pipelines, it helps engineers detect performance regressions and unsafe overload behavior before promoting a release.
Structured Logging
Structured logs attach explicit context, such as severity, job identifiers, processing stages, and error codes, to each event. This makes distributed data pipelines easier to troubleshoot, query, monitor, and test without depending on fragile text parsing.
Temporal Aggregation
Temporal aggregation turns streams of measurements or events into time-based summaries for dashboards, alerts, capacity planning, and historical analysis. Choosing the right interval and statistic determines whether engineers detect short-lived failures, interpret rates correctly, and retain useful information without unnecessary storage and processing costs.
Temporary Credentials
Temporary credentials let people and workloads access cloud resources without distributing permanent access keys. They reduce the lifetime of exposed credentials, support federation and role-based access, and shift credential renewal to identity services and supported client libraries.
Test Pyramid
The Test Pyramid balances automated test coverage against execution time, maintenance effort, and diagnostic clarity. In CI/CD pipelines, it helps engineers detect common defects early while reserving slower, more expensive tests for interactions and workflows that require deployed systems.
Time Series
Time series organize measurements such as CPU utilization, request counts, and response latency so engineers can analyze trends, detect anomalies, and evaluate operational thresholds. Effective cloud monitoring depends on identifying each series correctly, choosing suitable collection and aggregation intervals, and balancing historical detail against storage and query costs.
Timeline Reconstruction
A reconstructed timeline connects security alerts, identity activity, configuration changes, network traffic, and workload events into an evidence-backed incident narrative. It supports root cause analysis by distinguishing the initial compromise and enabling conditions from later attacker actions, symptoms, and response activity.
Trunk-Based Development
The shared trunk remains the authoritative integration point and is kept releasable through automated testing, rapid feedback, and prompt repair of failures. This reduces divergence and large merge conflicts while enabling CI/CD pipelines to promote validated changes consistently across application environments.
UI Testing
UI testing exercises visible controls, navigation, input handling, and displayed results to detect defects that lower-level tests can miss. In cloud delivery pipelines, automated UI tests provide release confidence by checking important user journeys against deployed applications before promotion.
Unit Testing
Unit tests check functions, methods, or small modules against explicit expectations using controlled inputs and dependencies. They provide fast feedback during development and help CI/CD pipelines reject regressions before code reaches deployed data, application, or machine learning workflows.
Version Control
Version control creates a traceable history for artifacts such as source code, infrastructure definitions, configuration, and AI prompts. It helps engineers collaborate safely, connect deployed behavior to specific revisions, and recover from changes that introduce errors or regressions.
Vulnerability Assessment
A vulnerability assessment determines which weaknesses exist, which resources they affect, and how urgently they need attention. In cloud environments, recurring assessments help engineers address vulnerable dependencies, exposed workloads, and insecure configurations as deployments and threat information change.
Waterfall Model
Waterfall emphasizes upfront requirements, documented designs, defined deliverables, and controlled transitions between development phases. Understanding it helps engineers distinguish lifecycle governance from CI/CD automation and recognize when sequential planning supports predictability or creates costly feedback delays.
Webhooks
A webhook lets an event producer send a request to a registered endpoint instead of requiring the consumer to repeatedly poll for changes. Engineers use webhooks to trigger builds and tests, integrate enterprise applications, and start asynchronous AI workflows, while explicitly handling authentication, retries, and duplicate deliveries.
Workflow Orchestration
An orchestrator maintains the execution state of a process and determines which task runs next, including parallel work, waits, retries, and exception paths. In cloud applications, this separates business coordination from individual functions and services, making integrations easier to operate, recover, and audit.
Workload Identity
Workload identity lets software prove who it is and receive permissions appropriate to its function and execution environment. Cloud implementations commonly combine runtime identity, federation, and short-lived credentials to reduce reliance on stored secrets while supporting least privilege and auditable access.
Services on the exam
The 81 AWS services the DOP-C02 exam covers.
Concepts on the exam
The 139 cloud concepts the DOP-C02 exam covers, each explained with the AWS services that implement it, in the Cloud Concepts Hub .